Enterprise Copilots
Persistent conversations and massive document repositories processed without re-reading context.
AI INFRASTRUCTURE · CONSTANT-MEMORY ARCHITECTURE
AVIKRAT is building a new paradigm for long-context LLM inference using compact persistent hidden states and local decoding — transforming linear context complexity into constant memory.
01 · THE BOTTLENECK
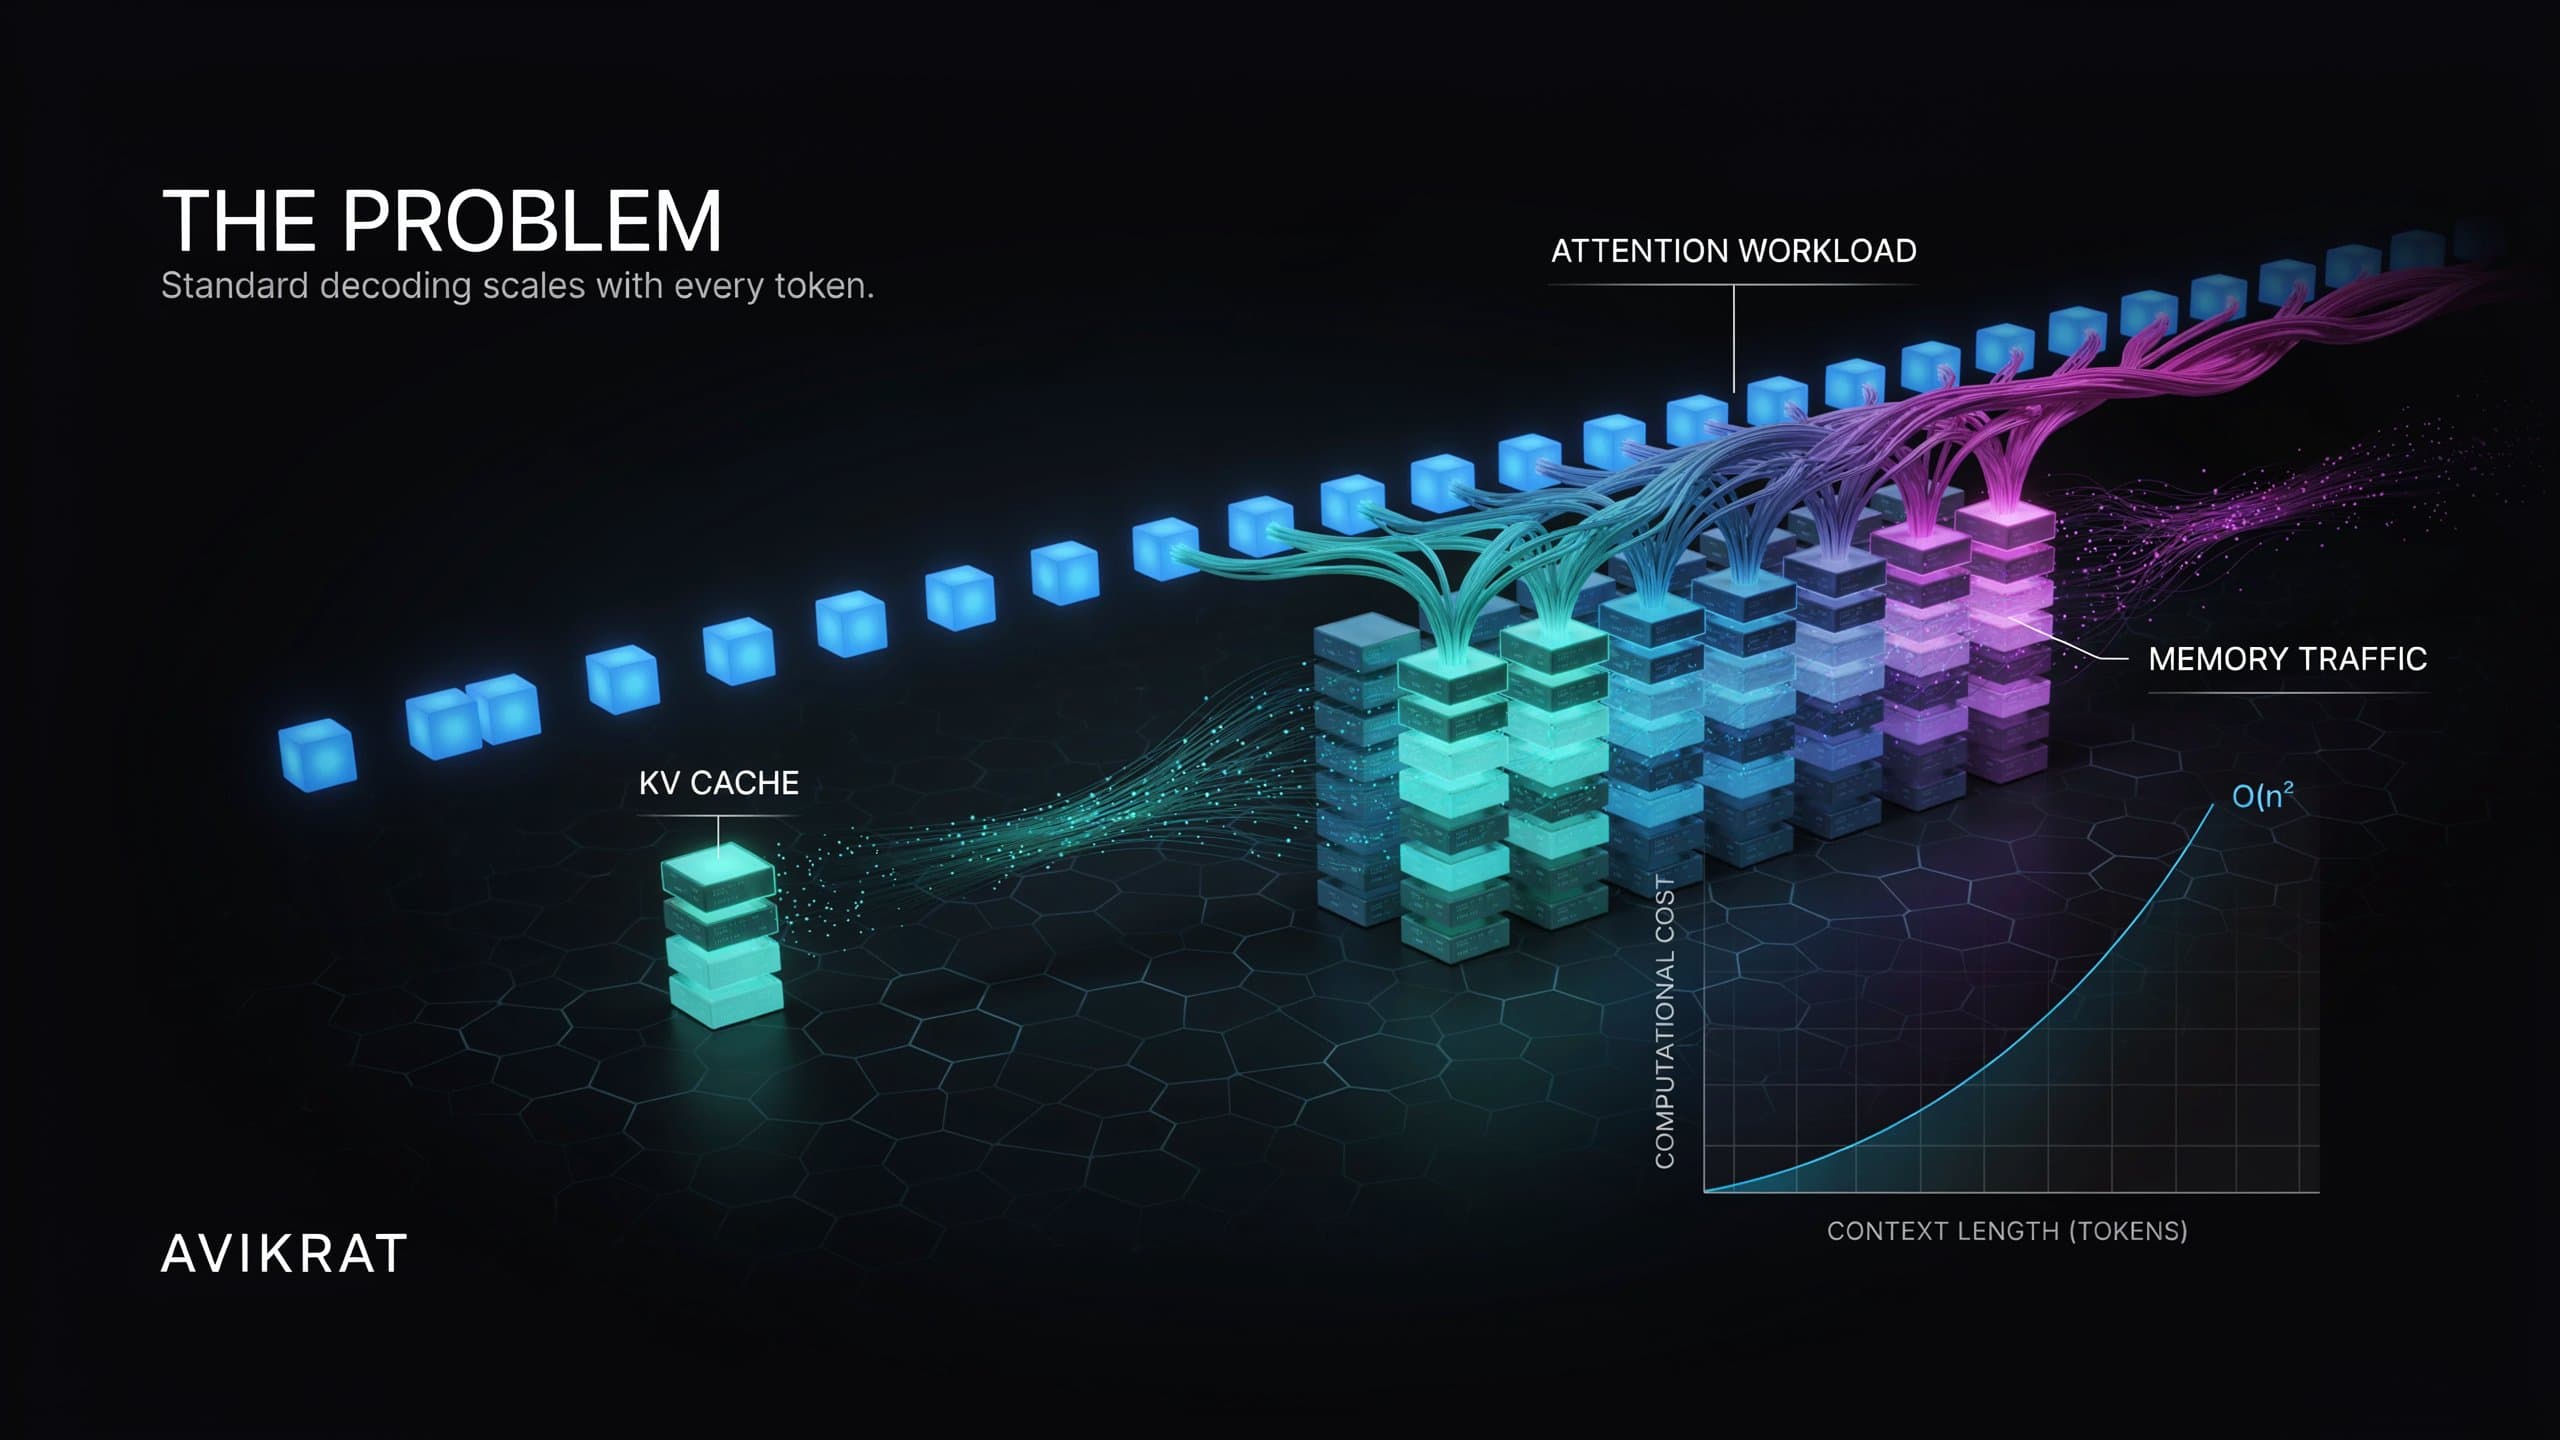
As context grows, standard decoding keeps expanding the KV cache. Attention cost and memory traffic climb linearly with context length — driving up compute cost and slowing latency on every turn.
02 · ARCHITECTURAL PARADIGM
History is encoded once into a compact persistent hidden state. Subsequent decoding operates strictly over a fixed local window — decoupling long-context processing from memory growth.
Historical context is compressed into a fixed-size, persistent hidden vector state.
Token generation consumes only a small sliding window alongside the persistent state.
GPU KV-cache memory footprint remains constant regardless of sequence length.
03 · PERFORMANCE MODEL
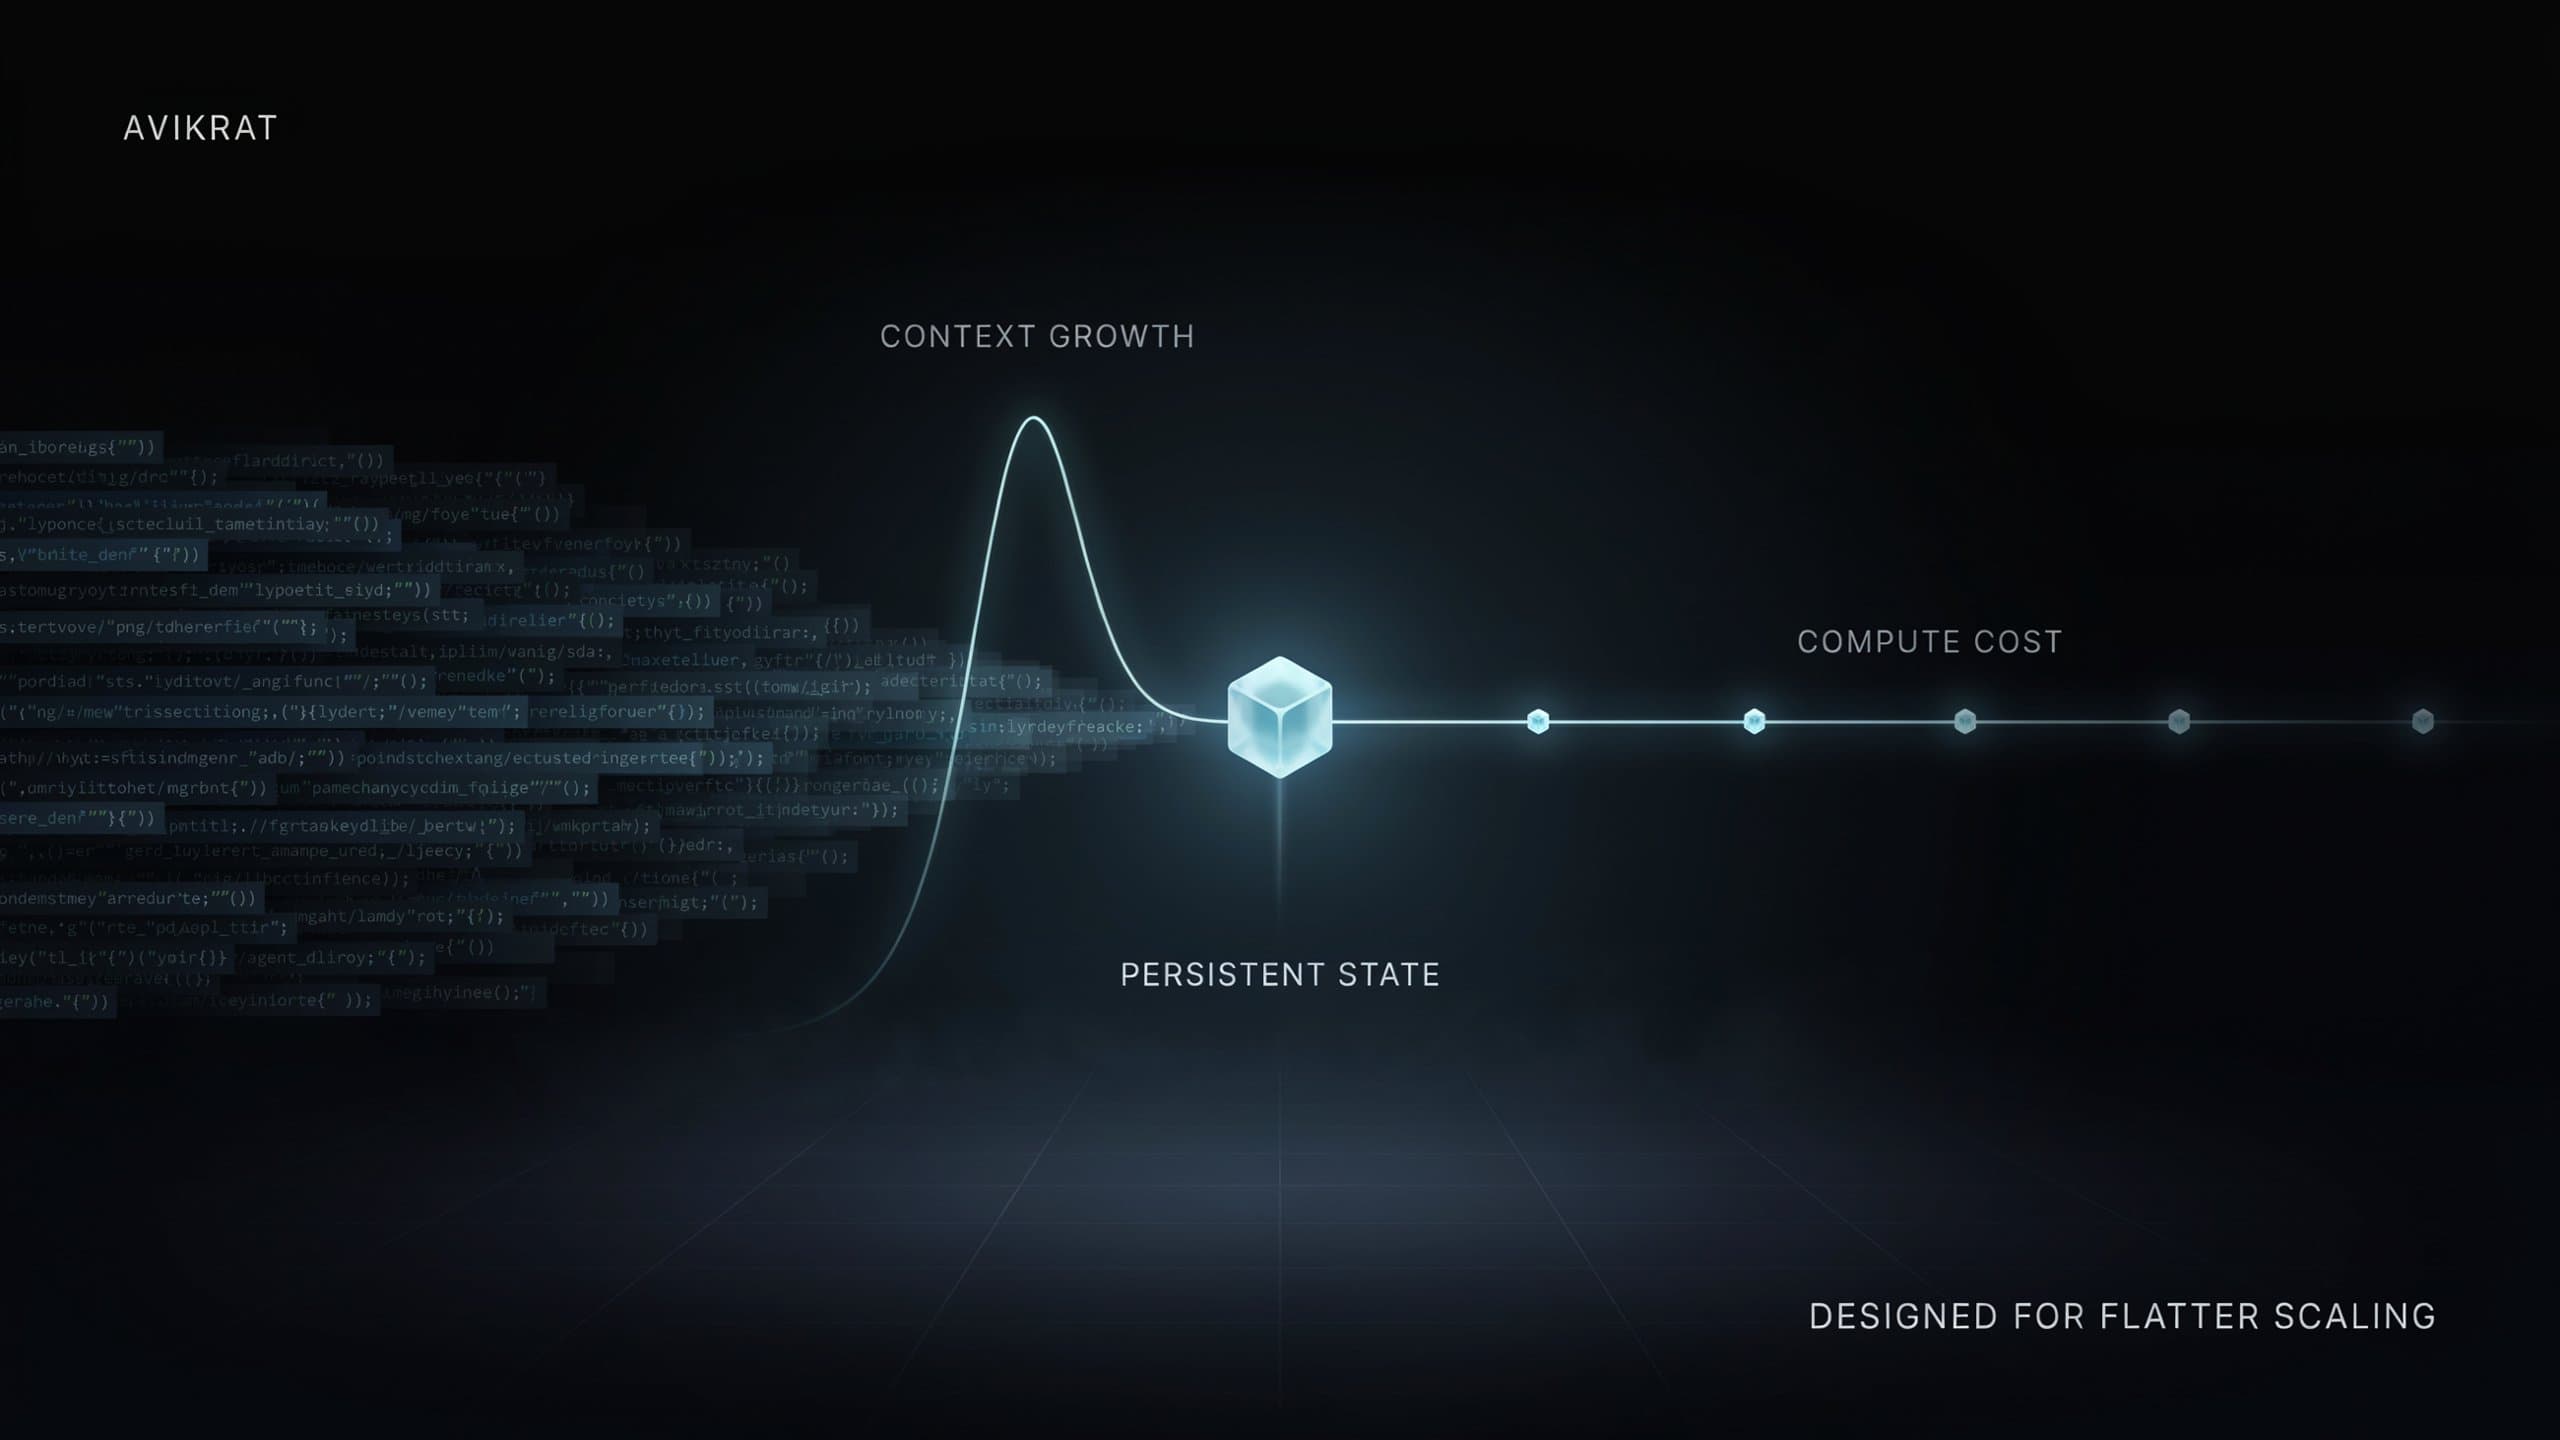
Context expands continuously. The cost baseline should remain fixed. By reading history once into a compact persistent state, AVIKRAT aims to keep per-token compute and memory overhead flat across extended sequence lengths.
ARCHITECTURE OBJECTIVE · SIMULATOR VALIDATION MODEL
04 · TARGET DOMAINS
Persistent conversations and massive document repositories processed without re-reading context.
Continuous long-context operation on memory-constrained edge hardware with flat memory overhead.
Long-running autonomous agent workflows maintaining a tight active window over historical state.
Bounded memory keeps real-time multi-hour continuous streaming inputs practical and cost-effective.
05 · EMPIRICAL VALIDATION
A working simulator models hidden-state structures and measures validation convergence. It serves as the architectural foundation for production-grade inference engine development.
SIMULATION PIPELINE · RESEARCH EVALUATION DIMENSIONS
Active Simulator Benchmarks
Compares simulated persistent state against observed attention context matrix structures.
Tracks state prediction deviation across high-depth token generation passes.
Measures directional alignment between compressed hidden vectors and full KV states.
Determines optimal sequence slicing intervals for long-context persistence.
06 · COLLABORATION & INITIATIVES
AVIKRAT is actively seeking research collaborators to validate the constant-memory architecture at scale, and enterprise partners to evaluate real-world production workloads.
07 · ADVANCED RESEARCH & COLLABORATION
AVIKRAT is developing computational architecture for AI systems that carry unlimited context without incurring the linear computational burden.